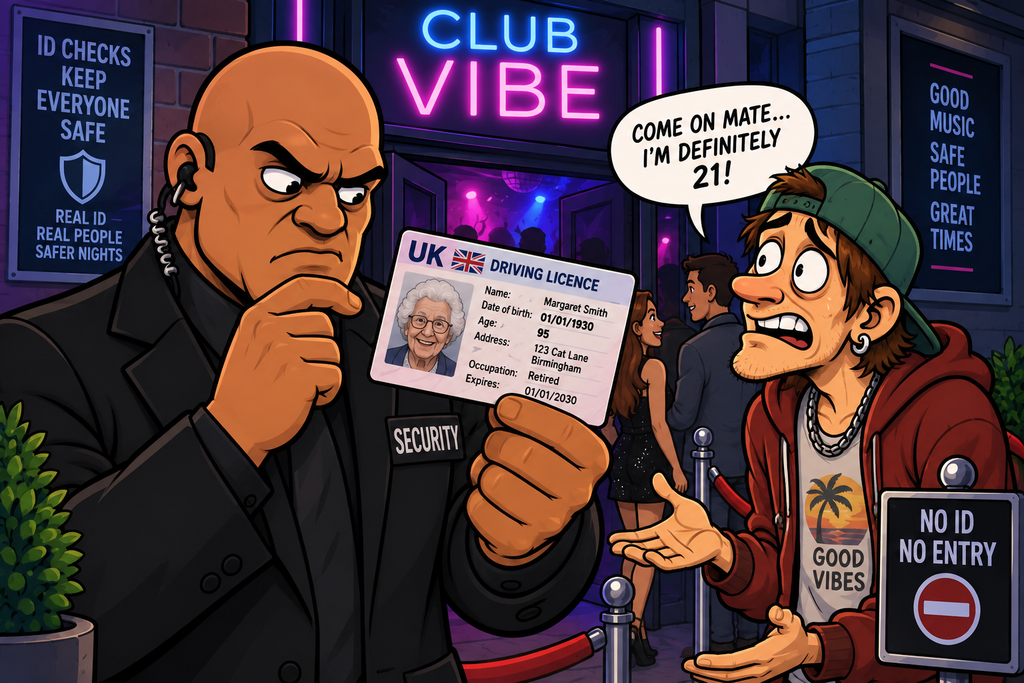
Imagine a bouncer on the door of a nightclub checking people as they enter.
The bouncer isn’t simply looking for one thing:
They might check:
- the ID for validity
- Is it genuine?
- Is it still in date?
- Are you allowed into this nightclub?
- Are you carrying anything you shouldn’t?
- Does the information on the ID make sense?
The bouncer is validating the input before allowing the person into the club.
Applications need to do the same thing with the data they receive.
Never assume that input supplied by a user, application, device or external system is safe – Validate it before using it.
Input validation is an important preventive security control and is particularly important when developing web applications, APIs, databases and other systems that accept data from outside sources.
What Is Input Validation?
Input validation is the process of checking data before an application accepts, processes or stores it.
The application determines whether the input:
- Has the correct type
- Has the correct format
- Is within an acceptable range
- Is the correct length
- Contains permitted characters
- Represents a valid value
- Meets the application’s business rules
For example, if an application asks for someone’s age and the user enters the value “23”, the system needs to check that the data is the correct type (e.g. an integer), and is within an allowed range (e.g. 18 – 65)
The application should not simply assume that the user has provided what was expected.
Why Is Input Validation Important?
Applications constantly receive information from outside themselves.
Examples include:
- Web forms
- URLs
- API requests
- HTTP headers
- Cookies
- File uploads
- JSON
- XML
- Network packets
- Database queries
- Configuration files
Any of these can potentially contain malicious input.
Without validation, attackers may be able to manipulate the application’s behaviour.
Never Trust User Input
One of the fundamental principles of secure application development is:
All external input should be considered untrusted until it has been validated.
That includes input from people who appear trustworthy – an application shouldn’t assume that because the user is authenticated, their input is safe.
A compromised administrator account could still send malicious data.
Input Validation Is Not Just About Hackers
Validation also protects against accidental errors.
Imagine a database expects:
Quantity: 1–100But a user accidentally enters:
1000000Without validation, the application might:
- Crash
- Overflow a value
- Process an enormous order
- Consume excessive resources
- Create incorrect records
Input validation therefore provides both security and reliability.
What Can Be Validated?
There are many different characteristics that an application can check:
Type Validation
The application should check that the data is the expected type.
For example:
- Integer
- Decimal
- Boolean
- Date
- Time
- String
- Email address
- JSON object
- Array
Type validation prevents unexpected data from reaching code that wasn’t designed to handle it.
Range Validation
Sometimes the type is correct but the value is unacceptable.
For example and age being entered as -20, or 150 should not be acceptable
This is particularly important for values which are subsequently used in calculations as the error will become componded.
Length Validation
Applications should often limit the length of input.
For example, it would be unlikely that a field which accepts the current year would be more than 4 characters long
An input containing thousands or millions of characters may indicate:
- A programming error
- An attempt to exhaust resources
- An attempt to bypass application logic
- An attack payload
Reasonable limits also reduce the risk of resource-exhaustion attacks.
Format Validation
Some data needs to follow a particular format.
Examples include:
- Email addresses
- Postcodes
- Telephone numbers
- Dates
- Account numbers
- IP addresses
For example an IPv4 address should be 4 sets of up-to 3 digits – e.g. 123.123.234.234
However, format validation needs to be designed carefully – Real-world data is often more complicated than a simple pattern suggests.
Character Validation
A very important consideration when conducting input validation is the format or encoding of characters
For example the application may allow A-Z, a-z, 0-9, + - * =, but not < > ! ' " ; &
This can reduce the opportunities for attackers to inject special characters into commands, queries or markup.
However, simply blocking a few characters is not a complete defence against injection attacks.
Allowlisting vs Blocklisting
There are two broad approaches to input validation.
- Allowlisting – Define what is permitted and reject everything else
- Blocklisting – Define what is forbidden.
Allowlisting is generally preferable where practical, because it can be very difficult to define every possible scenario of forbidden data
Attackers can often find alternative ways of representing malicious input that you haven’t thought about.
Syntactic Validation
Syntactic validation asks “Does the input have the correct structure?”
For example:
Date:

2026-09-10      ✓

2026-99-99      ✗
10/09/2026      ?
Hello           ✗
The input must follow the expected syntax.
Semantic Validation
Syntactically correct data does not necessarily imply that it is also meaningful.
For example 2026-09-10 is syntactically valid, but so is 2026-02-30. However there is no such data as the 30th February
Semantic validation asks “Does this value actually make sense?“
Business Rule Validation
Applications often need to enforce business rules as well.
For example:
Customer age: 15
Product: Alcohol

Format valid?       ✓
Number valid?       ✓

Business rule:
Customer must be 18+

                    ✗ REJECT
The input is technically valid data, but it simply isn’t valid for that particular operation.
Validation Should Happen at Trust Boundaries
A trust boundary is a point where data crosses from one security domain into another.
Examples include:
- Internet → Web server
- User → Application
- Application → API
- API → Database
- Cloud service → Internal system
Validation should happen when data crosses these boundaries as essentially, one domain is providing input to the other.
Client-Side Validation
A web application can validate input in the user’s browser. This means that the user receives immediate feedback to the validity of their input, and it saves server-side resources.
But there is a major problem – Client-side validation cannot be trusted as a security control.
If an attacker controls the client, then hey can simply bypass the client-side validation.
Server-Side Validation
The server must perform its own validation – Even if the browser says “Everything is valid”, the server should independently verify it.
Input Validation and SQL Injection
One of the best-known examples of malicious input is SQL injection.
Suppose an application builds a database query using user supplied input.
If input is handled incorrectly, an attacker may be able to manipulate the query to force the application to perform an undesired action
The result could include:
- Reading unauthorised data
- Modifying records
- Deleting data
- Bypassing authentication
Validation Isn’t the Main SQL Injection Defence
This is an important distinction – Input validation can help, but developers should not rely on validation alone to prevent SQL injection.
The primary defence is generally to use parameterised queries or prepared statements.
The database treats the supplied value as just data, rather than allowing it to become part of the SQL instruction.
The data is validated and then passed to the prepared statement and only the prepared statement is allowed to be processed.
This is an example of defence in depth.
Input Validation and Cross-Site Scripting (XSS)
Another major threat is Cross-Site Scripting – An attacker may attempt to place malicious script content into an web application such as a forum comment field.
Input validation can help prevent inappropriate content from being accepted, but again, validation alone isn’t enough.
Applications should also use:
- Context-aware output encoding
- Safe templating
- Content Security Policy
- Appropriate framework protections
Input Validation and Command Injection
Applications sometimes need to interact with operating-system commands. If user input is incorporated directly into a command, attackers may attempt command injection.
This can potentially allow an attacker to execute commands on the server.
e.g. Instead of presenting the user with data form the database, the malicious command may be able to extract user account information from the underlying operating system such as passwords.
The best defence is to avoid constructing shell commands from user input wherever possible.
If commands genuinely need to be used:
- Use safe APIs.
- Use fixed command structures.
- Validate arguments.
- Use allowlists.
- Avoid invoking a shell unnecessarily.
- Apply Least Privilege.
Input Validation and Path Traversal
Applications that accept filenames or directory paths can be vulnerable to path traversal.
For example, an application expects photo.jpg as a file to store in a database, but receives something attempting to navigate outside the intended directory such as script.php which contains the instruction to navigate to ../../../../etc/passwd
If the attacker can upload the php file and then execute it, the path traversal command may allow the code to reach out form the web application folder to the root of the underlying operating system, and then into the etc folder to read the contents of the passwd file.
Applications should avoid trusting user-supplied paths.
Safer approaches include:
- Allowlisting filenames.
- Mapping user identifiers to server-side filenames.
- Restricting access to a known directory.
- Canonicalising paths before checking them.
File uploads like this are particularly dangerous.
An application may allow users to upload:
- Images
- Documents
- Videos
- PDFs
But an attacker may attempt to upload executable content instead.
Simply checking the filename extension isn’t sufficient, as an attacker can rename a file.
A robust upload process may check:
- File extension
- MIME type
- File signature / magic bytes
- File size
- Content structure
- Malware scanning
Uploaded files should also ideally be stored somewhere that prevents them from being executed as server-side code.
Validate JSON and API Requests
Modern applications often communicate through APIs.
An API might expect something like:
{
  "name": "Sally",
  "age": 35
}
The API should validate:
- Required fields
- Data types
- Lengths
- Allowed values
- Nested structures
- Unexpected fields
For example:
API REQUEST
    │
    ▼
Schema validation
    │
    ├── Correct structure ✓
    ├── Correct types ✓
    ├── Required fields ✓
    ├── Valid ranges ✓
    └── Allowed values ✓
    │
    ▼
  PROCESS
Schema Validation
APIs can use a defined schema describing what valid input should look like.
For example:
name:
  string
  required
  max 100 chars

age:
  integer
  0–120

role:
  "user" | "manager" | "admin"
Anything outside the schema can be rejected.
This is much stronger than simply accepting arbitrary JSON.
Reject Unexpected Fields
Suppose an API expects:
name
email
telephone
An attacker sends:
name
email
telephone
isAdmin
If the API accepts arbitrary fields, unexpected data might accidentally influence application behaviour.
Where appropriate systems should reject fields that the application doesn’t expect.
This is particularly important for preventing certain forms of mass assignment vulnerabilities.
Input Validation and Authentication
Authentication doesn’t make input trustworthy – An authenticated user can still be malicious.
They may be:
- A compromised account
- An insider
- A malicious administrator
- A legitimate user attempting something they shouldn’t
Security controls should therefore remain layered.
Input Validation and Authorisation
Validation also shouldn’t be confused with authorisation.
Suppose a user submits:
Account ID = 12345The input may be perfectly valid. But does the user have permission to access account 12345?
That’s an authorisation question – Both checks are required.
Input Validation and Output Encoding
Input validation and output encoding solve different problems.
Input validation asks “Is this data acceptable?“
Output encoding asks “How should this data be safely represented in this particular context?“
For example, a user’s password might legitimately contain characters such as < > & ' "
Trying to reject every potentially dangerous character can cause usability problems. Instead, applications often need to encode data appropriately when displaying it.
Input Validation and Sanitisation
These terms are sometimes used interchangeably, but they describe different ideas.
Validation checks whether input meets the requirements.
Sanitisation attempts to modify input to remove or neutralise undesirable content.
For security-critical applications, validation and safe handling should be preferred over assuming that sanitisation will make arbitrary input safe.
Canonicalisation
Another important concept is canonicalisation. This is where the same value can sometimes be represented in multiple ways.
This is particularly important for:
- File paths
- Unicode
- URLs
- Encoded data
- Character representations
If an application validates one representation but processes another, an attacker may be able to bypass the validation.
Unicode and Encoding
Attackers may sometimes use different character encodings or Unicode representations to bypass simplistic validation.
Applications should therefore understand the encoding of the data they receive and normalise it appropriately before applying security checks where necessary.
See the blog about ASCII smuggling for an example of an attack that uses character encoding to bypass security systems
Regular Expressions
Regular expressions are often used for input validation.
For example, a simple pattern might check whether a value contains an expected structure.
They can be useful for:
- Simple identifiers
- Postcodes
- Reference numbers
- Restricted formats
But overly complicated regular expressions can themselves create security problems.
For example, poorly designed patterns can consume excessive CPU when processing specially crafted input. This is known as Regular Expression Denial of Service (ReDoS).
Validation Libraries
Developers don’t necessarily need to implement every validation mechanism themselves. Frameworks and libraries can provide:
- Schema validation
- Type validation
- Email validation
- URL validation
- File validation
- API validation
Using well-tested libraries can reduce implementation errors.
However a validation library still needs to be configured correctly.
Fail Secure
Input validation should generally follow a fail-secure approach. If the application cannot determine whether input is valid, it should not assume “It probably looks okay.”
When in doubt, don’t process it.
Error Messages
Validation errors should be useful to the user without revealing unnecessary information.
For example:
INVALID INPUT

The account number must
contain 8–12 digits.
is generally better than:
SQL ERROR:
SELECT * FROM customers
WHERE account_id = ...
The second response may reveal implementation details useful to attackers.
Don’t Rely on Hidden Fields
Web applications sometimes send information in hidden form fields.
For example:
<input type="hidden"
       name="price"
       value="99.99">
The fact that the field is hidden doesn’t make it trustworthy because an attacker can modify it.
The server must validate the value and, where appropriate, obtain authoritative information from its own data sources.
Don’t Trust HTTP Headers
HTTP headers can also be manipulated by clients.
For example:
User-Agent
Referer
X-Forwarded-For
Custom headers
These should not automatically be treated as trustworthy security information.
If an application relies on a header for a security decision, it needs to understand who can set or modify it.
Don’t Trust Cookies
Cookies are another form of client-controlled input.
A cookie might contain something like:
role=userbut what if an attacker alters the cookie data to read:
role=adminSecurity-sensitive information should be validated and protected appropriately, often using server-side session state and cryptographically protected tokens where suitable.
Rate Limiting and Input Validation
Validation can also help protect resources, but it isn’t a replacement for rate limiting.
Even invalid input can consume CPU, memory and network resources.
Attackers may deliberately submit enormous or computationally expensive input.
Examples include:
- Huge files
- Very large JSON objects
- Deeply nested structures
- Extremely long strings
- Expensive regular expressions
Validation should therefore include sensible limits.
Rate limiting and resource controls should therefore complement validation.
Input Validation and File Names
File names deserve special attention.
If an attacker can upload a file and then request that file to be executed, they could manipulate the system to perform an undesired action.
A safer approach is often to generate server-side filenames:
User uploads:
holiday.jpg

Server stores:
8f72c91a.jpg
The application doesn’t need to trust the user’s filename as a filesystem path.
Input Validation and Databases
Input validation should happen before data reaches the database, but databases should also have their own controls.
This provides multiple layers of protection.
Databases can enforce some forms of validation themselves.
Examples include:
- Data types
- NOT NULL
- UNIQUE
- CHECK constraints
- Foreign keys
For example:
Age INTEGER
CHECK (age >= 0 AND age <= 120)
If invalid data somehow reaches the database, the database can still reject it.
This is another example of Defence in Depth.
Input Validation and Logging
Rejected input can sometimes provide useful security information.
For example:
2026-09-10 16:20

User: Bob
Endpoint: /upload
Input: Invalid file type
Action: BLOCKED
Repeated malicious input like this could indicate an attack.
However, applications should be careful about logging the entire malicious payload, as this could affect log processing when examined.
Common Input Validation Mistakes
- Trusting client-side validation – The attacker can bypass it.
- Using only a blocklist – Attackers may find another representation.
- Checking only the filename extension – An attacker can rename a file.
- Validating after processing – The dangerous input may already have caused damage.
- Forgetting API endpoints – APIs are input sources too.
- Failing to validate length – Huge input can create resource exhaustion.
- Assuming authentication means trust – Authenticated users can still be malicious.
- Using validation instead of parameterised queries – Validation isn’t a replacement for proper database security.
- Modifying legitimate data – Over-aggressive sanitisation can corrupt valid information.
Input Validation as a Security Control
Input validation is primarily a preventive security control – Its purpose is to stop malformed, unexpected or dangerous data from reaching sensitive processing.
But it also supports:
- Detective controls through logging and monitoring
- Defence in Depth through multiple validation layers
- Secure by Design through defining safe inputs during development
- Least Privilege by limiting the consequences if something gets through
In Summary
Input validation is the process of checking external data before an application processes, stores or acts upon it.
It can include checking:
- Type – Is it a number, string, date, Boolean, object, etc.?
- Format – Does it follow the expected structure?
- Length – Is it within reasonable limits?
- Range – Is the value within an acceptable range?
- Characters – Are only permitted characters being used?
- Semantics – Does the value actually make sense?
- Business Rules – Is the value valid for the operation being performed?
- Structure – Does an API request match the expected schema?
Input validation should:
- Treat external data as untrusted.
- Be performed server-side.
- Prefer allowlists where practical.
- Validate at trust boundaries.
- Reject unexpected data.
- Apply sensible size and resource limits.
- Be combined with parameterised queries and output encoding.
- Be tested with malformed and malicious input.
- Be monitored and logged appropriately.
It is closely related to:
- Secure Coding
- Secure by Design
- Least Privilege
- Access Control
- Defence in Depth
- Application Security
- Database Security
And perhaps the most important distinction is this:
Input validation doesn’t make malicious input safe. It determines whether the input should be accepted in the first place.
A secure application doesn’t ask:
“Can I trust this user?”
It asks:
“Can I trust this input—and have I proved that it is valid before I use it?”
Don’t trust it. Validate it.